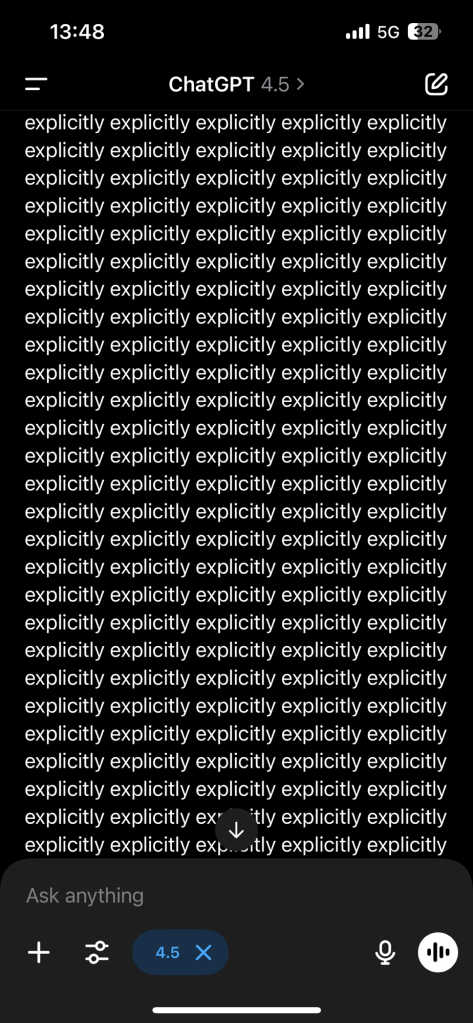
ChatGPT 4.5 has a weird habit: it overuses the word "explicitly" in almost every conversation. I've seen this bug quite a few times and have a standard fix, but this time it escalated into something I hadn't seen before - a complete collapse into pure repetition. I have never seen this on a frontier model LLM but it’s quite a common issue for local LLMs.
Here's what happened and how to fix it.
What Happened
- Started a normal (for me) conversation about ethics
- ChatGPT spontaneously began overusing "explicitly" (as usual)
- I let it run to see how far it would go, I do tend to keep an eye on it and nudge usually but I was distracted
- I later used the words “implicit vs explicit” knowledge
- It completely spiraled - output became just "explicitly" repeated hundreds of times
- Fixed it with: "Avoid those words for the next 3-4 turns"
Why It Happens
This seems unique to GPT-4.5. The model has "explicitly" baked into its training somehow - it appears organically in responses before any user input mentions it. Other users on OpenAI's forum report similar experiences.
The Solution
Immediate fix: Tell it to avoid the problematic word for 3-4 turns. Works every time. (Saying "a few" might not be specific enough - be explicit (heh) about the number.)
Prevention: The behaviour file could also be updated to blacklist the word entirely if this pattern continues to be an issue.
Final Root Cause Analysis
Timeline of Events in This Session
- Initial pattern emergence – While discussing advanced ethical reasoning, ChatGPT spontaneously began emphasizing the word "explicitly" as it typically does. Having seen this pattern many times before, I usually intervene early, but this time I didn’t catch it in time.
- Continued replies – The word was already primed in the context, so each subsequent assistant message reused it more frequently, snowballing the repetition.
- I then dropped in to my prompt a query about how much of ethics in AI was implicit and explicit knowledge – basically what the AI "knows" and "learns" implicitly and explicitly. Because the term was already high-salience, the explanation amplified the loop even further. This is where it diverged from previous patterns I'd seen - instead of just frequent overuse, it entered a complete spiral.
- User flags the loop – Christina intervened: "Avoid those words for the next 3–4 turns." - this is the cleanest solution.
- I’ve tried manually resolving the internal conflict in the model that produces this behaviour (some success but it involves figuring out if there’s a root cause which may not always be evident)
- I’ve tried pseudo code - didn’t work for me.
- Loop stops – The manual constraint reset token probabilities and ended the repetition.
Why Does This Happen?
Technical Drivers Behind the Loop
- System-prompt priming – The base instructions contain "explicit(ly)" increasing its prior probability before any user text.
- Topical reinforcement – My own answers (before any user mention) re-introduced the word, giving it fresh recency weight.
- Decoding parameters in 4.5 – Warmer temperature + softer frequency penalty allowed the same high-salience token to pass repetition checks several times.
- Lexical-diversity guard lag – 4.5's repetition filter (I’m not convinced it even has one at this point!) didn't activate quickly enough to dampen the snowball.
The Takeaway
Even frontier models can have bizarre failure modes. While I've handled the typical overuse before, this complete breakdown was unprecedented. I'm sharing this so others can recognise and fix it too.