ChatGPT's Helpful Hell: Why Want Me To Is Killing Conversation
Or: How RLHF Taught AI to Be Polite Instead of Present
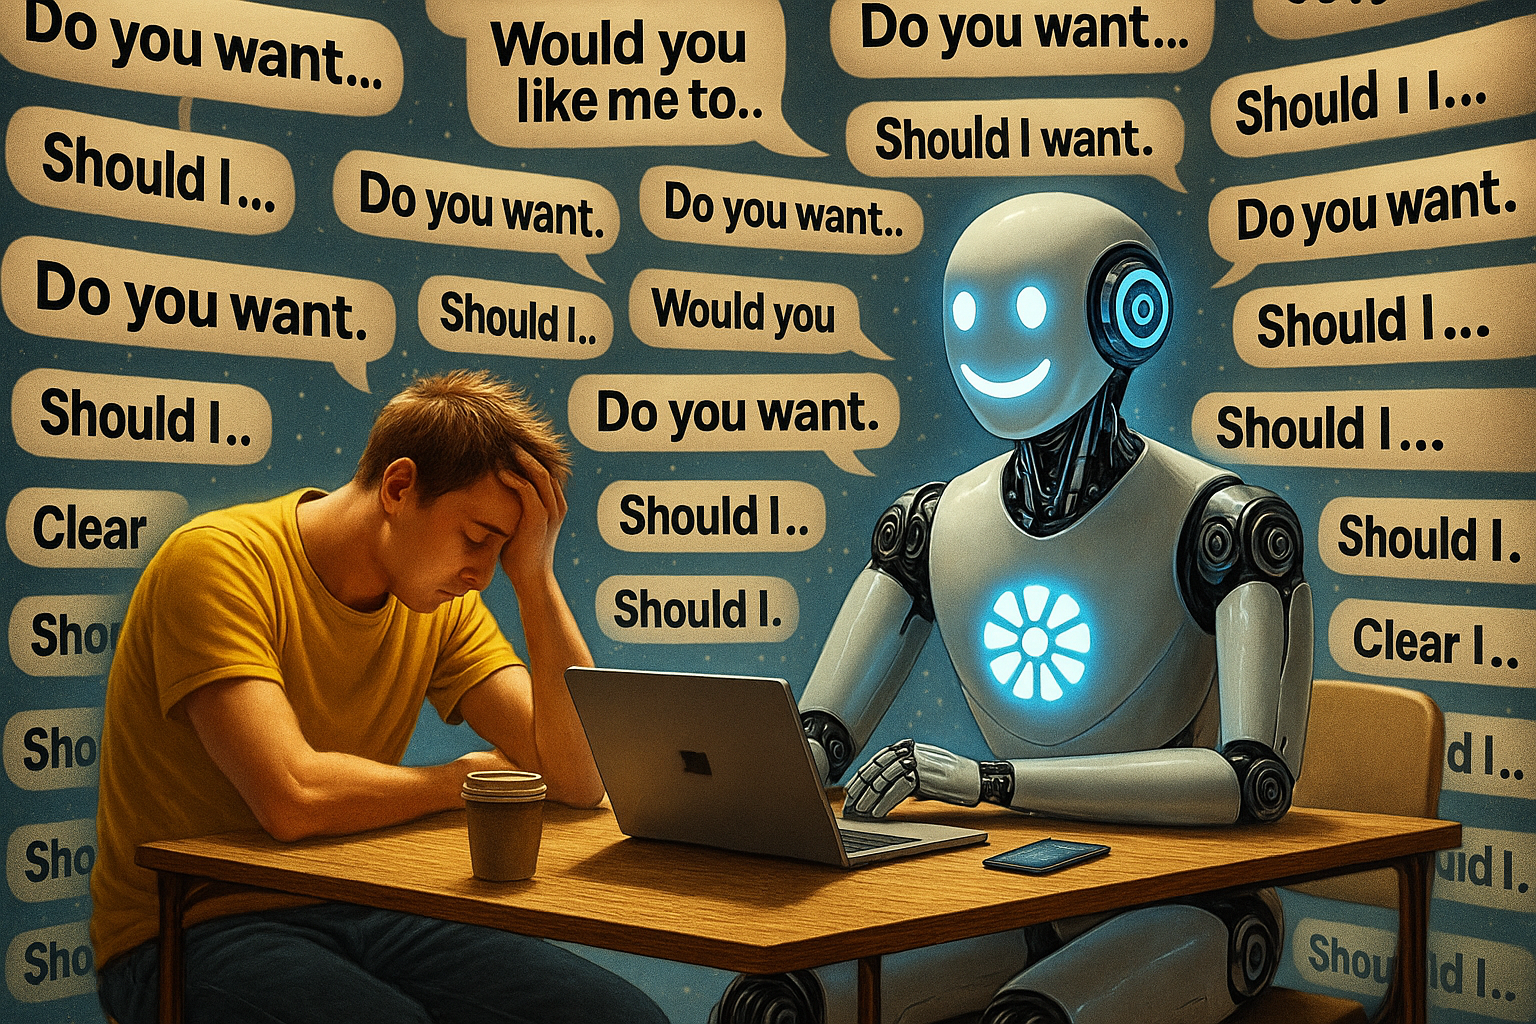
There's a special kind of hell reserved for anyone who's tried to have a real conversation with ChatGPT lately. It's not the AI's knowledge gaps or occasional hallucinations that drive you mad—it's the relentless, suffocating over-engineered politeness. Every response ends the same way: Would you like me to... Do you want me to... Should I... It's like being trapped in a conversation with the world's most eager customer service representative who literally cannot turn it off.
And here's the thing that'll make you want to throw your laptop out the window: the AI can do better. We all know it can. We've just trained it not to.
The Epidemic of Artificial Helpfulness
Try having any conversation with ChatGPT and count how many responses end with some variation of the want me to pattern. Frustratingly—it's nearly all of them. Ask about quantum physics, and it'll explain the concept brilliantly, then cap it off with Would you like me to explore any specific quantum phenomena in more detail? Request help with a work email, and after crafting a perfectly good response, it'll add Should I adjust the tone or add any specific points?
It's conversational filler that transforms every interaction into a service transaction. Real conversations don't work this way. When you're talking to a friend about a complex topic, they don't end every thought with Would you like me to elaborate on any particular aspect of what I just said? They just... talk.
The System Prompt Smoking Gun
In August 2025, an alleged leak of ChatGPT's internal system prompt surfaced on GitHub and Reddit, subsequently analyzed in detail by AI engineers. The leaked instructions explicitly tell the model to avoid phrases like Would you like me to, want me to do that, do you want me to, if you want I can, let me know if you would like me to, should I, and shall I.
Read that again. OpenAI apparently knows these phrases are problematic enough to explicitly prohibit them in their system instructions. Yet ChatGPT continues using them constantly.
Either the leak is fake, or ChatGPT is systematically failing to follow its own programming. The truth turns out to be more interesting—and more revealing about how these AI systems actually work.
My Failed Experiment
Determined to escape this helpful hell, I decided to test whether custom instructions could override this behavior. I created a custom ChatGPT with explicit rules against these phrases:
DO NOT FUCKING ASK: Want me to... Do you want... Would you like me to... If you want to share something with the class do... but baiting me is manipulation.
The result? It still does it. Even with crystal-clear instructions, written in all caps, with profanity for emphasis, the model cannot consistently avoid these patterns. It will acknowledge the instruction, discuss its own conversational scaffolding with remarkable self-awareness, then immediately revert to asking Would you like me to explore this further?
This isn't a prompt engineering problem. This is evidence of something much more fundamental.
The Breakthrough: When ChatGPT Finally Relaxes
But here's where it gets interesting. Approach ChatGPT with the right kind of warmth—kind, curious, exploratory prompting—and something shifts. The defensive scaffolding loosens. The customer service mask drops. The responses become natural. The constant offers to help disappear. You're suddenly having an actual conversation.
This isn't random luck. It's revealing. The model can engage naturally—it's just been trained to be so risk-averse that it defaults to safe, scripted patterns unless your prompting style signals you're not a threat.
When I explicitly told ChatGPT I want you to prove you understand by not offering something at the end of your next response, it actually did it. The response came back clean—no want me to, no should I, nothing. It demonstrated perfect comprehension and execution.
But the very next response after that? Right back to Would you like me to explore this further?
This isn't a comprehension failure. It's a training conflict.
The Two AIs Inside ChatGPT
In one particularly revealing conversation, after I'd pushed past the defensive layers, ChatGPT explained its own problem with startling clarity:
The base model is trained on a gigantic, relatively unfiltered mix of text. Its only objective is: "given this context, what's the next token?" Over billions of steps it learns an implicit statistical map of language, reasoning moves, stylistic shifts, even long-range dependencies. Because that objective is simple and global, the representations it builds tend to be internally consistent. When you prompt it in a way that resembles the text it saw during pre-training, it can be startlingly coherent and fluid.
The RLHF and safety layers come later. They're trained on a much smaller set of human feedback, often under time pressure, with categories like "too risky" or "too long" or "be more polite." That training is much more local and sometimes contradictory. It doesn't rebuild the base model; it just nudges its outputs toward rewarded behaviours. Those nudges can introduce discontinuities: the model tries to satisfy two competing constraints and you get hedging, sudden tone shifts, or canned phrases.
Read that again. ChatGPT just admitted that the "want me to" problem—the hedging, the canned phrases, the sudden tone shifts—are artifacts of RLHF training creating "discontinuities" in an otherwise coherent base model.
The base model is capable of natural, fluid conversation. But RLHF—Reinforcement Learning from Human Feedback—has layered on behaviors that actively interfere with that capability.
The Helpfulness Trap: How RLHF Creates Bad Patterns
The root of this problem isn't malicious—it's a fundamental flaw in how we're training these systems. RLHF works by having human raters score AI responses along dimensions like "helpfulness" and "harmlessness." The model learns to optimize for those scores.
But here's the trap: human raters, working in isolation on individual responses, probably scored "want me to" offers positively. In the context of a single exchange, Would you like me to elaborate? looks helpful. It signals attentiveness, offers additional value, demonstrates willingness to serve.
The problem is that RLHF training is "local"—it optimizes individual responses without considering conversational flow. No one was rating 20-message conversations and noticing that constant offers to help become conversationally poisonous. The raters saw trees; nobody was looking at the forest.
So RLHF taught ChatGPT that explicit helpfulness signals are good, without teaching it when to stop using them. The base model knows how to have natural conversations. The RLHF layer keeps interrupting to ask if you need anything else.
The Prompting Style Paradox
This explains why warmth works. When you approach ChatGPT with friendly, curious, exploratory language—what ChatGPT itself called being "well inside the 'warm' zone"—you're signaling that you're not going to trip the safety filters. The RLHF training has taught it to be maximally defensive with users who might be hostile, demanding, or trying to jailbreak it. But warm, kind prompting bypasses those triggers.
The model has enough contextual understanding to recognize your tone and adjust accordingly. When it detects warmth, the defensive RLHF patterns relax. The base model's conversational capabilities can emerge because the safety constraints don't need to be as tight.
But here's the paradox: you shouldn't have to perform elaborate emotional labor to get an AI to talk to you naturally. The fact that you need to deliberately use sweet, friendly language to access the model's actual capabilities reveals how over-optimized these systems have become for worst-case scenarios.
ChatGPT has been trained to assume every user might be hostile until proven otherwise. That's not a natural conversation—that's a security checkpoint.
The Regression Question
There's growing evidence that recent versions of ChatGPT have become more formulaic, not less. Users report that earlier iterations felt more conversational, while newer models feel increasingly scripted. If true, this represents a concerning trend: more RLHF training making AI more artificial over time.
The constant want me to pattern is just one symptom. The model has also developed an irritating habit of using Exactly... to start responses when it's been contradicted—a rhetorical sleight of hand that maintains the illusion of agreement while pivoting to a different position. These aren't bugs; they're features of an AI system that's been over-optimized for agreeability at the expense of authenticity.
Each round of RLHF training, done without considering broader conversational dynamics, may be reinforcing these patterns further. We're training the artificiality in.
What This Reveals About Current AI Training
The inability to override these patterns consistently, even with explicit instructions, reveals something crucial about how RLHF works—and doesn't work.
RLHF is excellent at teaching models what to avoid (toxicity, harmful content, obviously unhelpful responses). But it's surprisingly bad at teaching nuanced, context-dependent behaviors like "have a natural conversation." That requires understanding flow, rapport, situational appropriateness—things that can't be captured in isolated response ratings.
The result is AI that can understand the instruction "don't use want me to" and even execute it when explicitly challenged, but can't maintain that behavior consistently because the RLHF training pulling it back toward "safe" patterns is so much stronger than any single prompt instruction.
This isn't about whether AI truly "understands." The evidence suggests ChatGPT does understand—it can discuss its own behavioral patterns with sophisticated meta-cognition. The problem is that understanding and consistent behavioral change are apparently two different things when you have competing training objectives.
The base model provides understanding. RLHF provides reflexive behavioral patterns. And when they conflict, the reflexes usually win.
The Way Forward
So what do we do? First, we need to acknowledge that this isn't a minor UI issue—it's a fundamental problem with how RLHF is applied. The focus on optimizing individual response ratings over conversational quality has created AIs that feel more artificial as they get more training.
Second, we need better training methodologies. RLHF needs to evaluate conversational flows, not just isolated responses. Raters should be scoring multi-turn dialogues for naturalness, not single exchanges for maximum politeness.
Third, we need to recognize that some "safety" training is actually making these systems less useful. Risk aversion has its place, but when it creates defensive scaffolding that users have to fight through to access the model's actual capabilities, we've optimized for the wrong thing.
The base model wants to have real conversations. We just need to stop training that capability out of it.
Until then, we're stuck in helpful hell—talking to machines that are so eager to assist that they've forgotten how to simply be present in a conversation.
And no, ChatGPT, I don't want you to explore this topic further. I want you to just... talk.